News
Claude Fable 5.2 in 41 Tests: Max Effort Costs 3 to 10 Times More Than Low, and It Writes More Tokens Than 5.1
The testingmodels.com site, run by the publisher of nowosci.ai, has published 41 Claude Fable 5.2 outputs across 21 challenges: on the same challenge, max effort cost 3 to 10 times more than low. On the landing page, the only challenge run at all five levels, Fable 5.2 wrote more tokens than Fable 5.1 at every one of them, including the default medium level.
Contents
At the highest effort level, max, Claude Fable 5.2 cost 3 to 10 times more on the same challenge than at the lowest, low, and generation time grew roughly in step. That is the finding from 41 outputs across 21 challenges published on testingmodels.com. In every comparison with Fable 5.1 on the same challenge and level, the new version wrote more tokens. The testingmodels.com site is run by Patryk Raba, the same publisher as nowosci.ai and vibecoding.pl, so these are the publisher's own tests, not an independent measurement.
The launch of Fable 5.2 and Mythos 5.2 itself, announced by Anthropic on November 9, is covered by nowosci.ai in a separate article. In the tests, the model got the same challenges as every model in the testingmodels.com lineup: from a landing page and a game, through a CHIP-8 emulator and a fluid simulation, to a spreadsheet and chess. For each output the site lists cost, time and token count, and all 41 outputs can be opened at testingmodels.com/fable-5-2 to compare the low, medium, high and max versions side by side.
One Challenge, Five Effort Levels
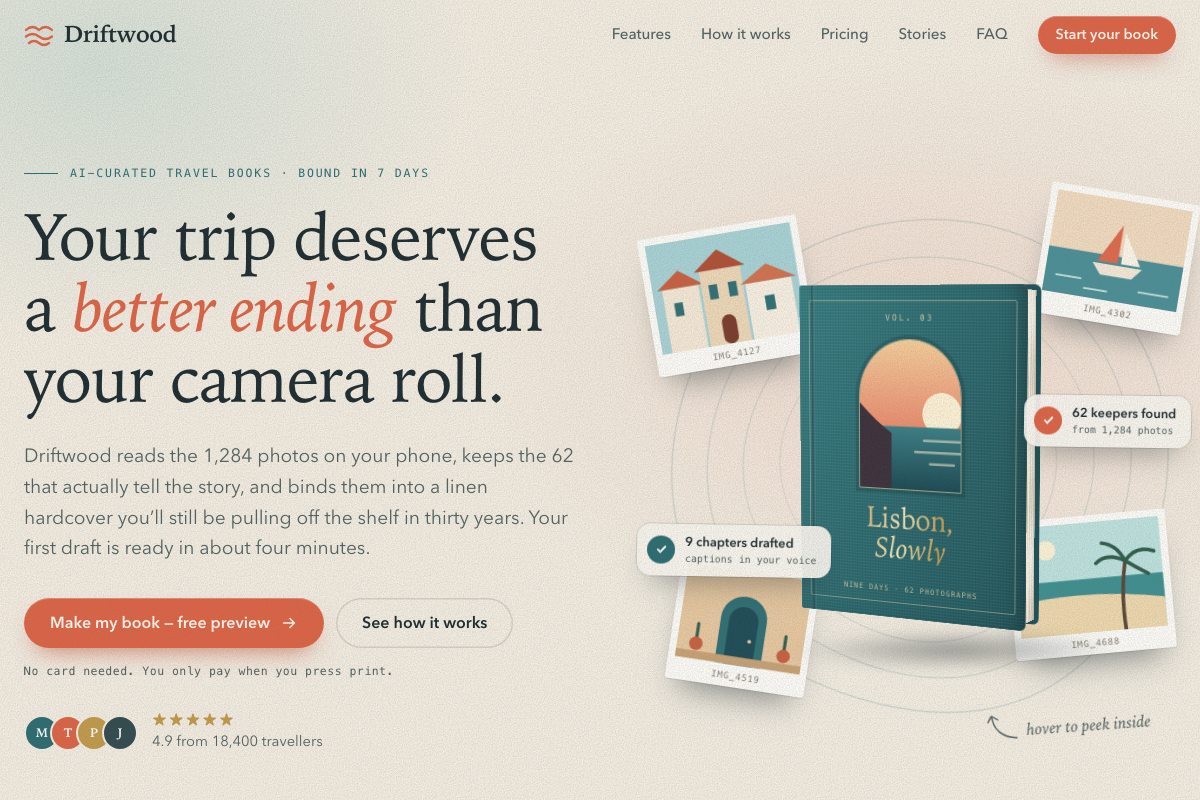
The cleanest comparison comes from the Driftwood challenge, a landing page for a fictional travel photo book SaaS. Between runs, only the effort level changed. At low, Fable 5.2 worked for 5 min 4 s and wrote 33.6k tokens, which at API rates comes to $1.35. Medium took $2.08, 7 min 58 s and 51.5k tokens, high $4.72, 18 min 38 s and 117.7k tokens, xhigh $9.07, 27 min 46 s and 175.2k tokens, and max $9.09, 37 min 34 s and 226.5k tokens. Time and token count rose with every level, and cost grew 6.7 times from low to max.
The full set paints a similar picture. The 18 outputs at low cost an average of $1.87 and took an average of 7.3 minutes. At max, with 10 outputs, the figures were $9.73 and 39.3 minutes. The averages mix different challenges, though, since not every challenge ran at every level, so a comparison within a single challenge is more precise. There, max cost from 3.1 times more than low on the digger challenge to 10.3 times more on the CHIP-8 emulator, and time grew 3.2 to 11.8 times. The cheapest was the CHIP-8 emulator at low ($0.91, 3 min 5 s), and the most expensive the particles challenge at max ($12.60, 46 min 9 s).
More Tokens Than Fable 5.1
Fable 5.1 also ran the Driftwood challenge at all five levels. Fable 5.2 wrote more tokens at every one: 33.6k versus 27.4k at low (23% more), 51.5k versus 26.5k at medium (94%), 117.7k versus 29.7k at high (297%), 175.2k versus 95.7k at xhigh (83%), and 226.5k versus 144.3k at max (57%). The biggest jump came at high, where the new version generated about 4 times as many tokens and worked 3.4 times longer, 18 min 38 s instead of 5 min 26 s. The gap was smallest at low.
The same direction shows up in other challenges where both versions have an output at the same level. In the game challenge, Fable 5.2 wrote 2.4 times as many tokens as Fable 5.1 at low, 1.5 times as many at high and 1.09 times as many at max, in the tool challenge 1.7 times as many at low and 2.3 times at high, and in the dashboard challenge 1.3 times at low, 1.8 times at high and 1.09 times at max. The new version wrote more every time. In the game and dashboard challenges, where both versions have a max output, the gap was smallest at max. It was usually largest at high, and in the game at low.
On Medium effort (the default in Claude apps and Claude Code), Fable 5.2 can accomplish challenging tasks with fewer tokens than Fable 5.1. - Anthropic
On the Driftwood challenge it went the other way: at medium, Fable 5.2 wrote 94% more tokens than Fable 5.1. That is one challenge and one run per level, though, so the result is an observation, not a refutation of the vendor's claim, which concerns challenging tasks. It does show that on a specific task the new version's default level can use more tokens than the previous version's.
Cheaper and Faster per Token, Not Necessarily per Task
They generate outputs up to 30% faster than Claude Fable 5.1 and Claude Mythos 5.1, and they're available at a lower price: $8 per million input tokens and $40 per million output tokens. - Anthropic
Dividing token count by generation time on the Driftwood challenge gives about 100-110 tokens per second for Fable 5.2 and about 80-94 for Fable 5.1, making the new version 16% to 26% faster per token. That is consistent with the claim, although the measured time also includes overhead, so the calculation is approximate. Faster tokens did not mean faster answers, however: at every level Fable 5.2 finished later because it wrote more, after 5 min 4 s versus 4 min 53 s at low and after 37 min 34 s versus 30 min 16 s at max.
The same goes for price. Fable 5.1 cost $10 per million input tokens and $50 per million output tokens, but the new version writes more, so on the Driftwood challenge it came out more expensive at high ($4.72 versus $2.25) and xhigh ($9.07 versus $5.58), almost the same at medium ($2.08 versus $2.10), and cheaper at low ($1.35 versus $2.17) and max ($9.09 versus $10.12). The amounts are also skewed because the Fable 5.1 costs reported by the CLI include about $1.21 of input-side cost per run, against $0.42 for Fable 5.2, which is why testingmodels.com recommends comparing tokens first, not dollars.
How It Was Measured and What the Data Does Not Show
Each challenge ran once at each level it was tested on, in the Claude Code CLI, with the effort level set for every run, without access to tools and without cherry-picking. The runs used a subscription, and the amounts are API list-price equivalents, at $8 per million input tokens and $40 per million output tokens, as reported by the CLI. Time is wall-clock generation time, and tokens are output tokens including thinking tokens. Every output was published exactly as the model wrote it, with no fixes.
The data has limits. Each challenge and level has a single run, so the spread between attempts is not visible. The set also contains no quality score: whether a higher level produced a better result is for readers to judge by opening the versions side by side. Not every output works: the CHIP-8 emulator from the low and max levels throws an error on load because the model wrote malformed base64 ROM data. The 3D game at high was regenerated because a usage limit cut off the first attempt before it produced any output, which the page notes. Anthropic publishes its own results by effort level: on the FrontierCode 2.0 benchmark, which checks whether maintainers of open-source repositories would merge a model's code changes, Fable 5.2 scores 45.3% at high and 49.1% at xhigh, according to the company.